I Tried Ready-Made DESIGN.md in Codex and Claude Code
12-minute video for Premium members. I found a useful library of DESIGN.md examples, and compared it to generally prompting Codex / Claude Code with their design / front-end skills.
Fresh insights on AI-powered development
12-minute video for Premium members. I found a useful library of DESIGN.md examples, and compared it to generally prompting Codex / Claude Code with their design / front-end skills.
6-minute video for Premium members. A quick test how the new GPT-6-Astra performs in Codex/ChatGPT app: how expensive is the Browser Use, and is it worth switching to Light level for saving money?
7-minute video for Premium members. I tested Sol vs Opus as code REVIEWERS, running the same prompt 8 times: 4 on Opus, 4 on Sol, also on different thinking levels of Medium/High. Is there a clear winner?
7-minute video for Premium members. Experiment: what if I benchmark models not on ONE prompt, but on the set of FOUR prompts? I tried this approach with 5 top LLMs, which scored the best?
After looking my LLM benchmarks table, many people ask how exactly I am testing models, and what are the evaluation criteria. To not repeat it in every video, I decided to publish this article, explaining my metholodogy.
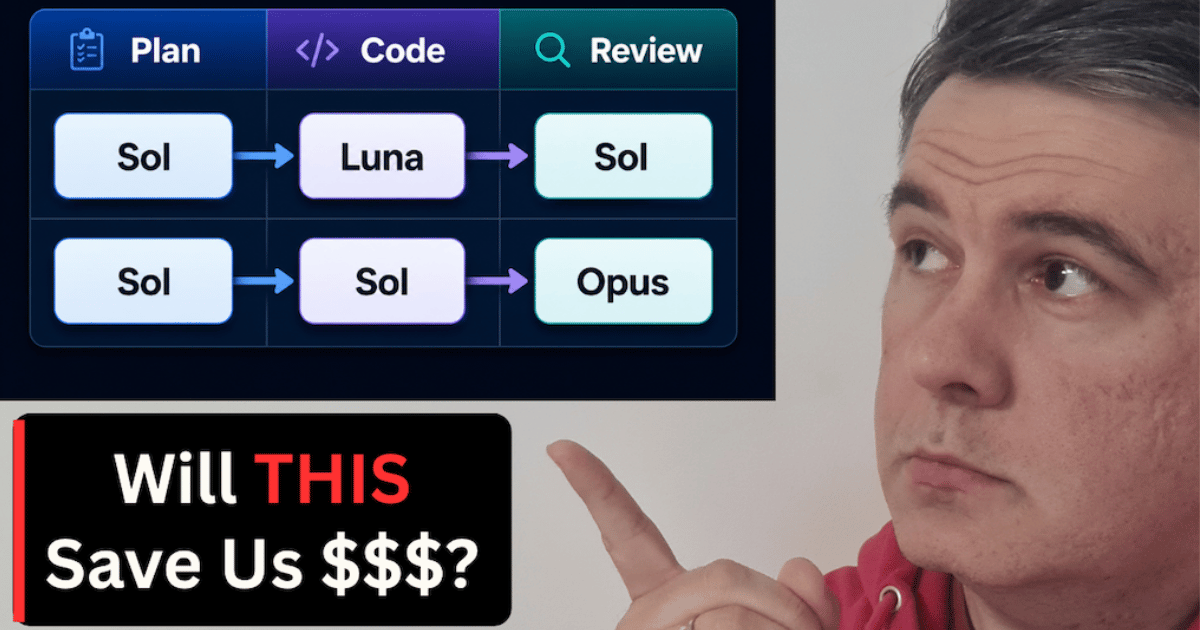
12-minute video for Premium members. Luna is much cheaper than Sol, so can we save money/time to prepare the plan with Sol, give implementation to Luna, and then review with Sol again? Let me show you the numbers from my experiment.
I've been using Grok 4.5 in OpenCode for my LLM benchmarking, but now, as Cursor is bought by the same company, would it make sense to use Cursor with Grok? I've tried, and here are the summarized results, in the video.
6-minute video for Premium members. I decided to test whether harness can change the results - so is DeepSeek v4 Flash in Codex CLI better/worse in terms of quality/price/speed than in OpenCode?
People say local LLMs are getting better for coding. I decided to test how they work in practice, with a few experiments, without investing in extra hardware. In this article, I will show tests on `google/gemma-4-e4b` and `Qwen2.5-Coder-14B-Instruct-GGUF` models.
8-minute video for Premium members. I added Kimi K3 to the previously-executed benchmark, where frontier LLMs had to fix 3 complex bugs in big open-source projects.