I Asked LLMs To Review Code TWICE: Which "Team" Found Most Bugs?
9-minute video for Premium members. I performed the same review with 4 LLM combinations: Opus + Opus (review AGAIN), Opus + Sol, Sol + Sol, and just Astra. Which performed the best?
Fresh insights on AI-powered development
9-minute video for Premium members. I performed the same review with 4 LLM combinations: Opus + Opus (review AGAIN), Opus + Sol, Sol + Sol, and just Astra. Which performed the best?
11-minute video for Premium members. New v1.3 from very popular Matt's skills adds /retro to improve how your agent will work in the FUTURE sessions after the current one. I've tested before/after on a real project.
10-minute video for Premium members. I saw a tweet about all LLMs writing too much code, and decided to test Astra / Sol / Opus / Sonnet / Grok on that criteria. And also, is all "bloatware" really bad?
15-minute video for Premium members. I asked Opus/Astra to prepare AUDIT.md file of the existing codebase, and the approach/process/cost of the audit was SURPRISINGLY different.
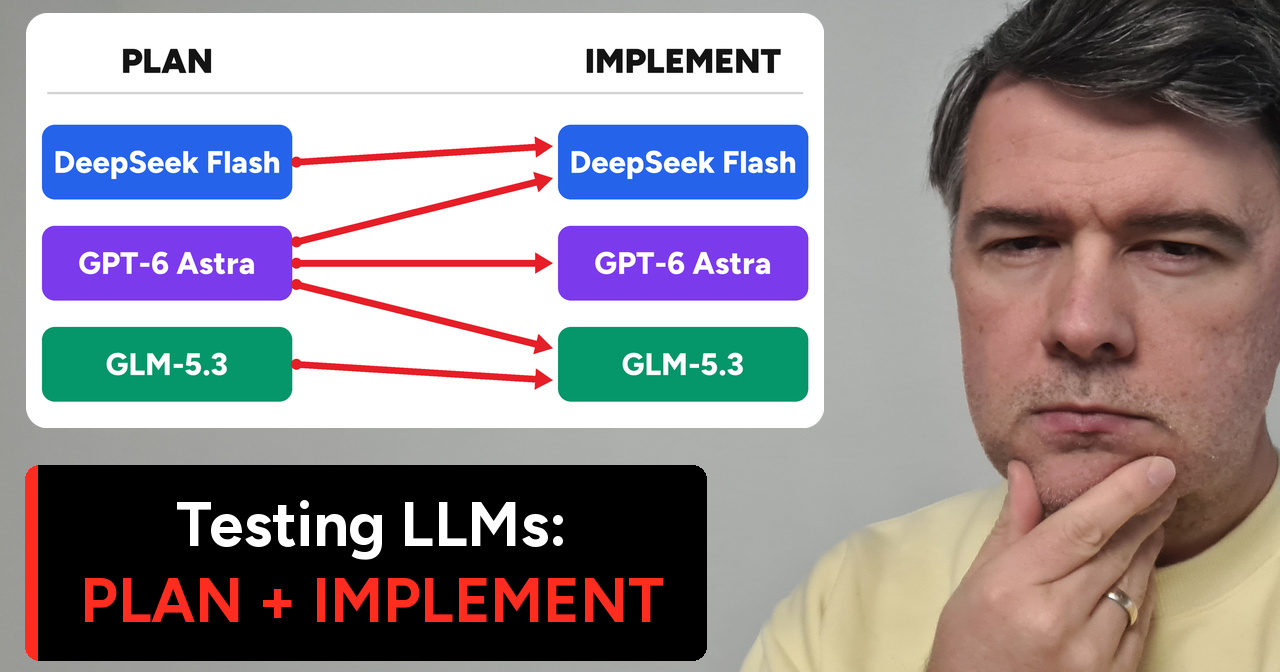
21-minute video for Premium members. I tested 5 different scenarios of the same project plan+build: can we save tokens on using a cheaper model for implementation, after Astra builds the plan? Or maybe LLMs got good enough for PLANNING, too?
12-minute video for Premium members. I gave the same prompt with Luna Max model executed in 4 different harnesses. Was there any difference in code quality or things how AI agents did along the way? Speed? Cost?
12-minute video for Premium members. I found a useful library of DESIGN.md examples, and compared it to generally prompting Codex / Claude Code with their design / front-end skills.
6-minute video for Premium members. A quick test how the new GPT-6-Astra performs in Codex/ChatGPT app: how expensive is the Browser Use, and is it worth switching to Light level for saving money?
7-minute video for Premium members. I tested Sol vs Opus as code REVIEWERS, running the same prompt 8 times: 4 on Opus, 4 on Sol, also on different thinking levels of Medium/High. Is there a clear winner?
7-minute video for Premium members. Experiment: what if I benchmark models not on ONE prompt, but on the set of FOUR prompts? I tried this approach with 5 top LLMs, which scored the best?